High Availability
High Availability
As more and more mission-critical applications move on the Internet, providing highly available services becomes increasingly important. One of the advantages of a clustered system is that it has hardware and software redundancy, because the cluster system consists of a number of independent nodes, and each node runs a copy of operating system and application software. High availability can be achieved by detecting node or daemon failures and reconfiguring the system appropriately, so that the workload can be taken over by the remaining nodes in the cluster.
随着越来越多的关键任务应用程序在Internet上移动,提供高可用服务变得越来越重要。群集系统的优点之一是它具有硬件和软件冗余,因为群集系统由许多独立的节点组成,并且每个节点运行操作系统和应用程序软件的副本。可以通过检测节点或守护程序故障并适当地重新配置系统来实现高可用性,从而可以由群集中的其余节点接管工作负载。
In fact, high availability is a big field. An advanced highly available system may have a reliable group communication sub-system, membership management, quoram sub-systems, concurrent control sub-system and so on. There must be a lot of work to do. However, we can use some existing software packages to construct highly available LVS cluster systems now.
事实上,高可用性是一个很大的领域。先进的高可用系统可能具有可靠的组通信子系统,成员资格管理,quoram子系统,并发控制子系统等。一定有很多工作要做。但是,我们现在可以使用一些现有的软件包来构建高度可用的LVS集群系统。
Working Principle
In general, there are service monitor daemons running on the load balancer to check server health periodically, as illustrated in the figure of LVS high availability. If there is no response for service access request or ICMP ECHO_REQUEST from a server in a specified time, the service monitor will consider the server is dead and remove it from the available server list at the load balancer, thus no new requests will be sent to this dead server. When the service monitor detects the dead server has recovered to work, the service monitor will add the server back to the available server list. Therefore, the load balancer can automatically mask the failure of service daemons or servers. Furthermore, administrators can also use system tools to add new servers to increase the system throughput or remove servers for system maintenance, without bringing down the whole system service.
通常,负载平衡器上运行有服务监视器守护程序,以定期检查服务器的运行状况,如LVS高可用性图中所示。如果在指定时间内没有来自服务器的服务访问请求或ICMP ECHO_REQUEST的响应,则服务监视器将认为该服务器已失效,并将其从负载平衡器的可用服务器列表中删除,因此不会向该失效服务器发送新的请求。当服务监视器检测到死服务器已恢复工作时,服务监视器会将服务器添加回可用服务器列表。因此,负载均衡器可以自动屏蔽服务守护程序或服务器的故障。此外,管理员还可以使用系统工具添加新服务器以增加系统吞吐量或删除服务器以进行系统维护,而不会降低整个系统服务。
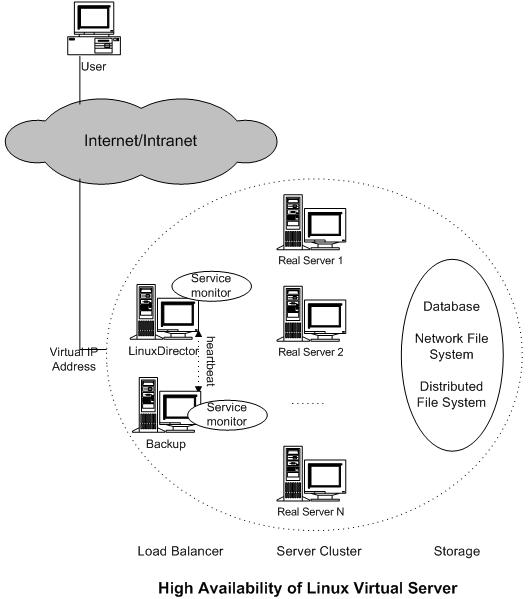
Now the load balancer might become a single failure point of the whole system. In order to prevent the whole system from being out of service because of the load balancer failure, we need setup a backup (or several backups) of the load balancer. Two heartbeat daemons run on the primary and the backup respectively, they heartbeat the message like “I’m alive” each other through serial lines and/or network interfaces periodically. When the heartbeat daemon of the backup cannot hear the heartbeat message from the primary in the specified time, it will take over the virtual IP address to provide the load-balancing service. When the failed load balancer comes back to work, there are two solutions, one is that it becomes the backup load balancer automatically, the other is the active load balancer releases the VIP address, and the recover one takes over the VIP address and becomes the primary load balancer again.
现在,负载平衡器可能会成为整个系统的单个故障点。为了防止整个系统由于负载均衡器故障而无法使用,我们需要设置负载均衡器的备份 (或多个备份)。两个心跳守护程序分别在主备份和备份上运行,它们通过串行线路和/或网络接口周期性地使诸如 “我还活着” 之类的消息心跳。当备份的心跳守护进程在指定的时间内无法听到来自主服务器的心跳消息时,它将接管虚拟ip地址以提供负载均衡服务。当发生故障的负载均衡器恢复工作时,有两种解决方案,一种是它自动成为备份负载均衡器,另一种是活动负载均衡器释放VIP地址,恢复者接管VIP地址,再次成为主负载均衡器。
The primary load balancer has state of connections, i.e. which server the connection is forwarded to. If the backup load balancer takes over without those connections information, the clients have to send their requests again to access service. In order to make load balancer failover transparent to client applications, we implement connection synchronization in IPVS, the primary IPVS load balancer synchronizes connection information to the backup load balancers through UDP multicast. When the backup load balancer takes over after the primary one fails, the backup load balancer will have the state of most connections, so that almost all connections can continue to access the service through the backup load balancer.
主负载平衡器具有连接状态,即连接转发到哪个服务器。如果备份负载平衡器在没有这些连接信息的情况下接管,则客户端必须再次将其请求发送到access service。为了使负载均衡器故障转移对客户端应用程序透明,我们在IPVS中实现了连接同步,主IPVS负载均衡器通过UDP组播将连接信息同步到备份负载均衡器。当备份负载平衡器在主负载发生故障后接管时,备份负载平衡器将具有大多数连接的状态,因此几乎所有连接都可以通过备份负载平衡器继续访问服务。
The availability of database, network file system or distributed file system is not addressed here.
这里不涉及数据库,网络文件系统或分布式文件系统的可用性。
Working Examples
There are several software packages in conjuction with LVS to provide high availability of the whole system, such as Red Hat Piranha, Keepalived, UltraMonkey, heartbeat plus ldirectord, and heartbeat plus mon.
有几个软件包与LVS一起提供整个系统的高可用性,例如Red Hat Piranha,Keepalived,UltraMonkey,heartbeat plus ldirectord和heartbeat plus mon。
The following examples of building highly available LVS systems are only for reference.
以下构建高可用LVS系统的示例仅供参考。
-
Using heartbeat+mon+coda to build highly available LVS systems
-
Using heartbeat+ldirectord to build highly available LVS systems
There must be many other methods to build highly available LVS systems, please drop me a message if you have your methods.
必须有许多其他方法来构建高度可用的LVS系统,如果你有你的方法,请给我留言。